Key takeaways
- Anthropic published “The components of agent memory” on November 6, 2026. It describes agent memory as experience retained across sessions, distinct from model weights, in-context learning and compaction.
- The proposed hierarchy has four layers: searchable transcripts, agent-written notes, representations such as wikis, and a small amount of context injected into every session. Anthropic calls offline passes that reorganize or correct these layers “dreaming.”
- In one internal 25-question test over roughly 350,000 files and 420 million tokens, Anthropic reports that search plus a growing wiki reached 61% versus 53% for search alone and used about 20,000 fewer tokens per question. This was a small, private, vendor-run evaluation, not an independent benchmark.
- The report also documents failure modes: stale notes sent a game-playing agent into a loop, a wiki could become larger than its source documents, concurrent writers dropped contract facts, and injected memory consumes context while spreading errors.
- Treat memory as a derived, fallible index over immutable evidence. Preserve source transcripts, attach provenance and freshness, limit what is injected, isolate concurrent writes, and require a representative test before paying for background consolidation.
Anthropic published the agent-memory design on November 6
Anthropic’s Engineering team published “The components of agent memory” on November 6, 2026. This is not a new Claude model, a new API identifier or a pricing announcement. It is a first-party engineering report about how Anthropic is designing memory for agents that work across sessions, with examples from Claude Managed Agents and Claude Code.
The report uses a narrower definition than the word “memory” often gets in product marketing: information learned from interactions or tasks and saved as readable context for later sessions. It explicitly excludes trained model weights, learning inside one conversation and compaction summaries that replace earlier turns within a long session.
The design separates transcripts, notes, representations and injected context
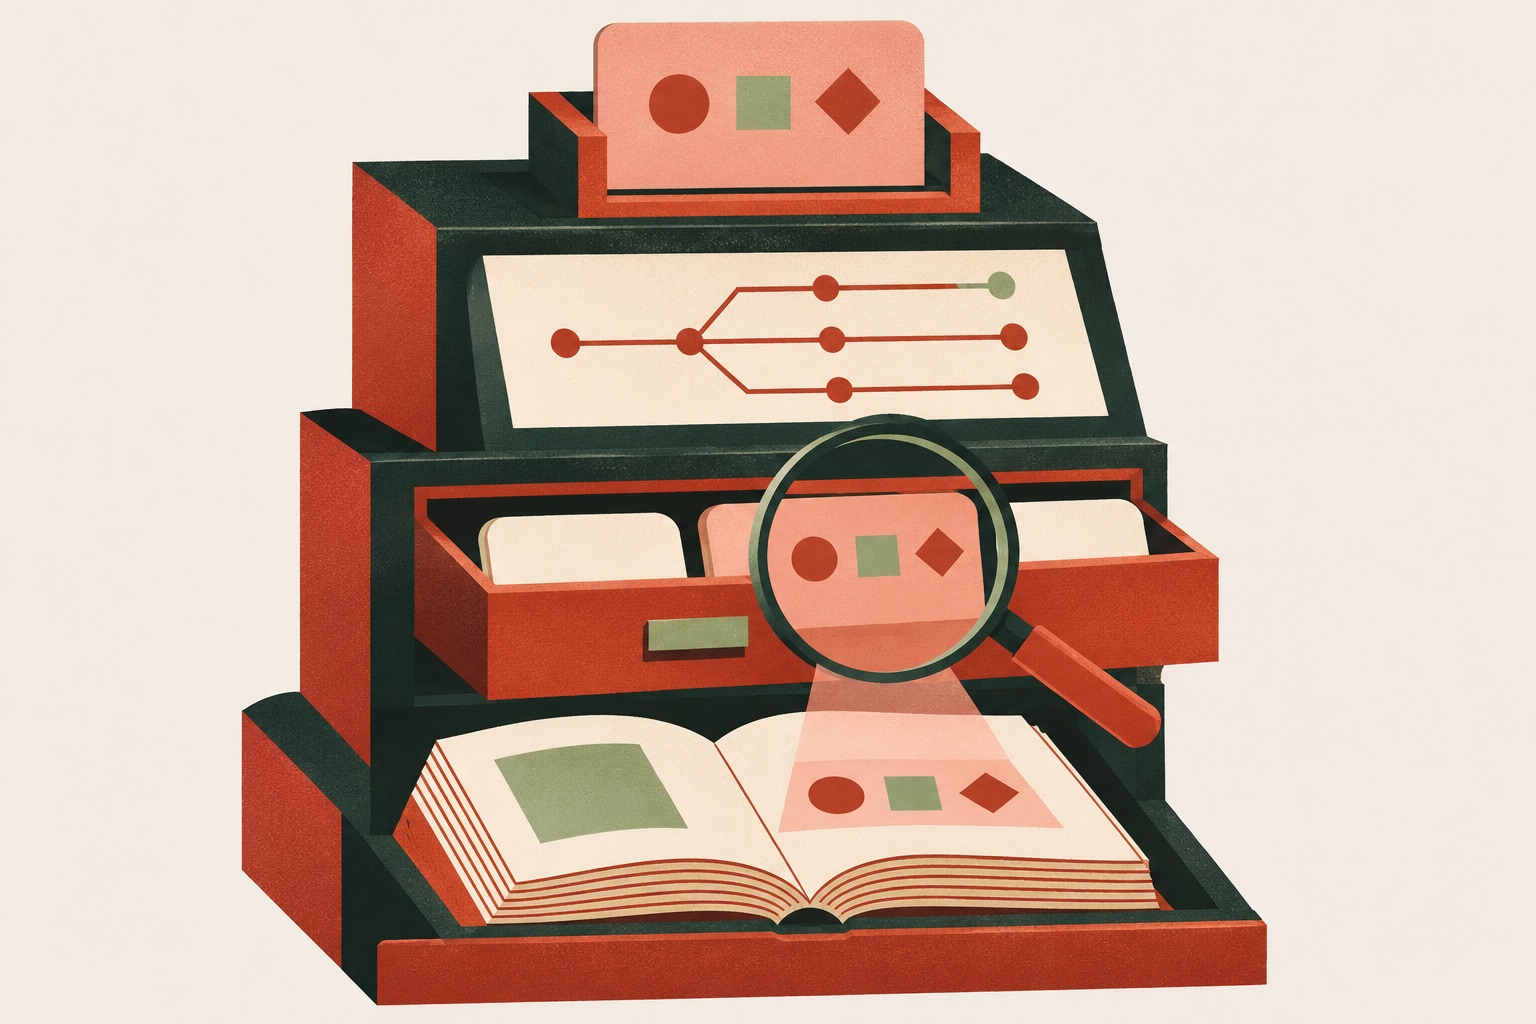
At the bottom sits a searchable event log: the transcripts that preserve what happened. Above that are memory notes written during work, then representations such as linked wikis that organize many records, and finally a deliberately small layer loaded into every new session. The layers solve different retrieval problems and should not be collapsed into one giant prompt.
Anthropic calls background passes over logs and memory “dreaming.” A pass can test a note against a transcript, create or prune notes, build navigation structures, or promote a compact index into the next session. The name is metaphorical; the mechanism is additional model inference over stored records, so it has compute cost and can introduce its own errors.
Newer Claude models reportedly learned better memory habits
On a CL-Bench database task, each question started in a fresh session but the agent retained a memory directory. Anthropic says Sonnet 4.6 generated untested theories, Opus 4.7 consolidated notes and tracked confirmation, and Opus 5 plus later Opus 5.5 and Sonnet 5.5 closed a loop of recording validated rules and traps. The public article’s chart carries the scores; the prose does not provide a complete table or uncertainty estimates for every model.
The report’s Pokémon example makes salience concrete. Around 10,000 steps, Sonnet 3.7 had written 413 files in 225 folders and earned one badge. Fable 5 wrote nine files in two folders plus one top-level dashboard and earned four badges; Opus 5.5 reportedly used a similarly compact approach and beat the game. These are illustrative runs—not controlled proof that one memory policy caused the outcome—and Anthropic says it compared one run from Sonnet 3.7 with one from Fable 5.
Prescriptive memory rules sometimes hurt the stronger models
Anthropic reports that telling Opus 4.7 and Opus 5 to “record only failures” removed much of the performance gain they otherwise got from memory. General availability of a memory folder was enough for stronger models to choose what to keep, while Sonnet 4.6 benefited from explicit reminders to read its memory and test its theories; Anthropic says that intervention nearly doubled its score.
That does not justify letting an agent save anything without governance. It suggests that an application should separate content policy from salience micromanagement: enforce allowed data, provenance, permissions, retention and review, while testing whether a capable model chooses useful notes better than a rigid record-every-X rule.
Dreaming corrected one stale note, but the example exposes the trust risk
In a Pokémon run, Claude incorrectly recorded the location of a landmark near Mt. Moon. The stale note caused repeated navigation failures and the uncorrected run never reached the next city. Anthropic then ran a dreaming pass that compared the note with the session transcript, rewrote it and enabled the agent to progress to Cerulean City.
The result is useful because the transcript supplied a more authoritative record than the derived note. Production memory needs the same hierarchy: immutable source events, a pointer from every summary to its evidence, conflict handling, freshness metadata and a repair path. Re-reading an unproven summary with another model is not validation if the source record is absent or poisoned.
A private 420-million-token corpus showed a modest wiki gain over search
Anthropic built a wiki over about 350,000 internal files—roughly 420 million tokens—from Stainless, using 128 sequential Opus 5 sessions and a 25-question evaluation. It reports that wiki-only performance rose from 13% to 48% of graded criteria as construction scaled from two to 128 sessions. Search plus the wiki rose from 54% to 61% as the wiki grew, compared with 53% for search alone, and saved about 20,000 tokens per question.
Those numbers are directional evidence, not a general retrieval benchmark. The corpus and questions are private, the sample is 25 questions, and the article does not expose case-level outputs, confidence intervals, maintenance cost or an independent replication. On a separate legal task dominated by single-document retrieval, Anthropic says the wiki showed no clear gain; in another, the wiki became larger than the source collection.
Concurrent memory writers lost facts until the structure changed
In a contract task, several agents wrote into one shared table and only 41 of 57 graded facts survived. Anthropic then used a failure-reflection loop to change the instructions: one agent owned each contract page and quoted terms rather than compressing them into a shared summary. The rebuilt wiki retained 57 of 57 facts.
This is an agent-systems lesson as much as a prompting lesson. Shared mutable memory needs ownership, concurrency control, atomic updates, conflict detection and source-preserving fields. A better prompt may reduce collisions in one task, but it does not replace storage guarantees or tests for dropped and overwritten facts.
Injected memory must stay small and auditable
Anthropic warns that loading memories into every session spends context and propagates incorrect notes. Its linked Claude Code documentation says auto memory loads only the first 200 lines or 25 KB of MEMORY.md, using the header as an index to material stored elsewhere. That is a product-specific limit, but the broader design is portable: inject a compact map and fetch evidence when needed.
Keep mandatory policy separate from learned memory, because a mutable memory file should not silently redefine permissions. Track who or what wrote each item, its source, confidence, last validation and expiry. Scan retrieved content as untrusted input, and prevent external documents or user messages from promoting themselves into durable instructions.
What agent builders should do next
Start with transcript search and a small persistent note store before commissioning autonomous wiki maintenance. Freeze representative cross-session tasks, compare stateless, search-only, notes and maintained-representation variants, and measure accepted outcomes, retrieval accuracy, stale-note failures, context use, background-model cost, latency and human repair. A richer memory layer should earn its complexity against search.
Ship only if every derived memory can be traced to evidence and revoked, and if the configured system beats the simpler baseline on repeated workload-shaped tests. Trial when the gain is promising but maintenance cost or error propagation is unresolved. Reject durable memory for data that cannot be retained, and pause automatic promotion whenever provenance, access control or update conflicts cannot be enforced.
Copy-ready agent-memory evaluation record
Use this to compare a simple searchable log with notes, maintained representations and injected context without hiding the cost or trust boundary of each layer.
Entries stay in this browser tab and are not submitted to AccessAllGPT. Blank responses are copied as [Unresolved].
Tasks, users, number and spacing of sessions, decisions that depend on prior experience, consequence and success criteria.
Immutable transcripts or events, allowed data classes, retention, access controls, integrity checks and deletion path.
Search index, notes, wiki or graph, injected index; exact writer, reader, size limit, update cadence and storage location.
Source pointer, author, model and prompt version, timestamp, confidence, validation status, expiry and conflict rule for every item.
Untrusted-content handling, prompt-injection controls, permissions, secrets filtering, tenant isolation and prohibited promotion into instructions.
Stateless, search-only, notes and maintained-representation variants; repeated cases, graders, uncertainty and stop conditions.
Accepted outcomes, retrieval errors, stale or poisoned notes, context tokens, background compute, latency, storage and human repair.
Validation cadence, drift detection, concurrent-write handling, rollback, rebuild from source and incident owner.
Ship, bounded trial, simplify or reject; eligible workloads, ceilings, unresolved evidence, expiry and re-evaluation trigger.
Primary sources
Browse the publication-wide evidence index →
- The components of agent memoryAnthropic Engineering · Reviewed: November 6 publication metadata; memory notes; CL-Bench and Pokémon evaluations; steering; memory correction; wiki construction; context injection; goal-focused memory; limitations and open questions · Retrieved · Supports: Anthropic describes a four-layer memory design—transcripts, notes, representations and injected context—and reports internal evaluations of writing, correcting and reorganizing Claude agent memory with offline “dreaming” passes.
- Continual Learning Bench 1.0Continual Learning Bench Team · Reviewed: May 4 release metadata; benchmark purpose; task design; analysis and evaluation; domain-expert process; systems and tasks · Retrieved · Supports: The benchmark team describes CL-Bench 1.0 as sequences of expert-validated tasks where a system is expected to change over time, and says it compares cumulative reward, cost and gain against stateless systems.
- Manage memory in managed agentsAnthropic documentation · Reviewed: Memory directory behavior and persistence boundary linked from Anthropic’s research article · Retrieved · Supports: Anthropic documents the persistent memory directory used by managed agents; this establishes the product mechanism referenced in the evaluation, not the general effectiveness of memory.
- Manage Claude’s memoryClaude Code documentation · Reviewed: Auto-memory loading behavior and MEMORY.md limits linked from Anthropic’s research article · Retrieved · Supports: Anthropic documents that Claude Code loads only the first 200 lines or 25 KB of MEMORY.md as an index rather than injecting all auto-memory into every session.
Limitations
This is a source-backed briefing on a first-party Anthropic engineering report, not an independent memory-system evaluation. AccessAllGPT did not run Claude Managed Agents, Claude Code, CL-Bench, Pokémon, the Stainless corpus or Harvey LAB; access the private corpora, prompts, trajectories, memory folders, wikis, grading rubrics or model outputs; reproduce any score, token saving or game outcome; evaluate variance across repeated runs; inspect compute, latency or dollar cost for dreaming; test another provider or model; or audit the security and privacy of Anthropic’s implementations. Several examples compare small numbers of runs, the Stainless test used 25 private questions, and the report does not provide complete uncertainty estimates or public artifacts for every result. Product behavior and documentation can change.
Disclosures
AccessAllGPT received no Anthropic credentials, Claude access, managed-agent account, private data, evaluation artifacts, briefing, review, payment or compensation for this article. Anthropic and the cited benchmark team did not sponsor, review or endorse it. AccessAllGPT did not use, test, score or rank the named Claude models. AccessAllGPT Research is operated by NeuralArc, is independent, and is not affiliated with Anthropic or the Continual Learning Bench team. Publication-wide relationships are listed on the disclosures page.