Key takeaways
- AWS published a Codex-on-Bedrock rollout guide on November 11, 2026. It documents an existing inference path; it does not announce a new model or establish the first availability date.
- Codex remains on the developer workstation. Supported OpenAI models run through Bedrock; the native path uses IAM Identity Center and AWS credentials rather than a separate model-provider key.
- The article’s example uses openai.gpt-5.6-sol in Codex and us.openai.gpt-5.6-sol for its direct Bedrock Runtime check. Confirm model, account, Region and inference-path access separately.
- Native access is the suggested small-pilot default. AgentCore Gateway and LLM gateways add different routing, Guardrails or request-policy options, with additional configuration and operational responsibilities.
- The guide announces no new price or benchmark. Client token metrics are not a bill, and connecting through AWS does not move local tools into a managed cloud sandbox.
What AWS published
On November 11, 2026, AWS published “OpenAI Codex on Amazon Bedrock,” a practical guide for connecting the coding agent to supported OpenAI models through AWS identity and inference infrastructure. The main change for readers is a documented enterprise rollout path: native AWS access, a managed AgentCore gateway, or an organization-operated LLM gateway. AWS recommends starting with native access for a small, least-privilege pilot.
This is not a new Codex model launch. AWS says developers already use Codex with Bedrock, and the post does not establish when that support first became available. It also announces no new token price, context limit or performance benchmark. The available materials are the published guide and linked open-source configurations; successful use still depends on the deployed Codex version, approved model, AWS account, Region and inference path.
Codex stays local; model requests go to Bedrock
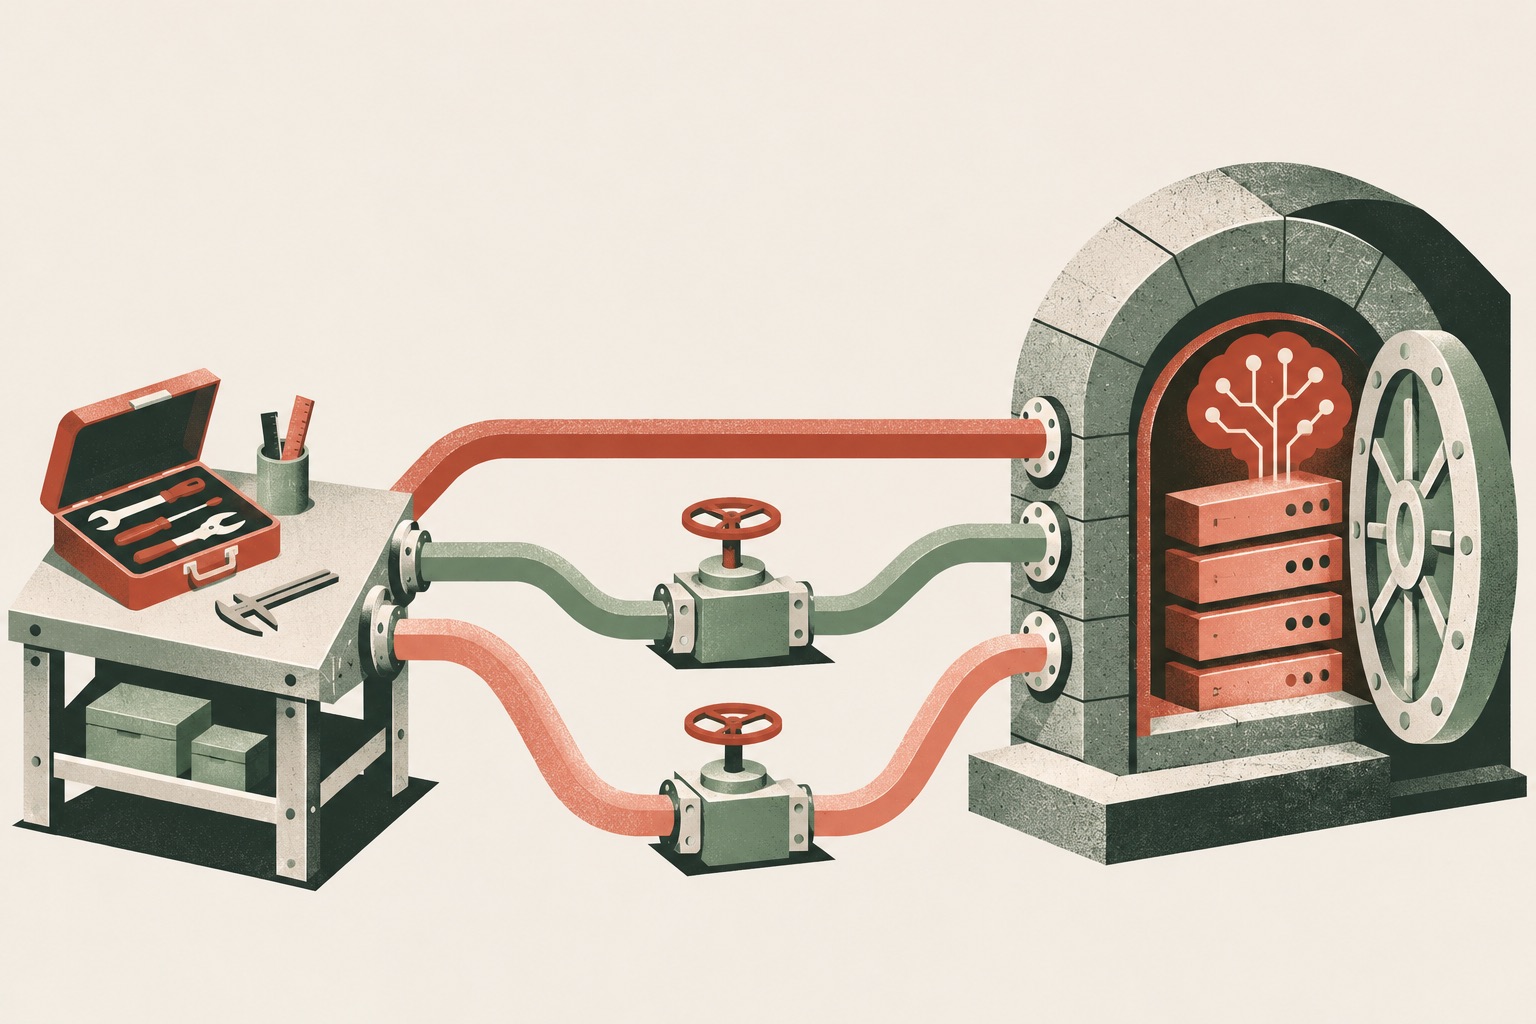
In all three designs, Codex runs on the developer workstation. The reference repository describes the gateway loop explicitly: Codex sends task context and tool definitions, a gateway forwards model requests to Bedrock, and Codex executes requested tools locally before sending their results in another turn. This is an inference-routing choice, not a hosted development environment or an automatic sandbox for shell commands.
For native access, the repository says Codex’s built-in amazon-bedrock provider signs requests with AWS SigV4 using the standard credential chain and IAM Identity Center. AWS’s example signs the user in with aws sso login --profile codex-bedrock and configures model_provider = "amazon-bedrock", model = "openai.gpt-5.6-sol", and the profile and Region under model_providers.amazon-bedrock.aws.
Keep the identifiers distinct. The blog’s direct Bedrock Runtime Converse check uses us.openai.gpt-5.6-sol in us-east-2, while its Codex configuration uses openai.gpt-5.6-sol. These are the article’s examples, not interchangeable IDs for every API. AWS tells readers to check Sol, Terra and Luna separately for their chosen account, Region and inference path. The guide is not evidence that the newest generation is supported everywhere.
Three rollout choices, not one mandatory gateway
Native AWS Access is the simplest documented starting point when workforce identity and IAM controls meet the pilot’s requirements. An existing identity provider provisions users and groups into IAM Identity Center, which issues temporary AWS credentials. The native quickstart labels its monitoring as soft: alerts rather than blocking. A token dashboard should not be mistaken for a hard spending limit.
AWS positions AgentCore Gateway as the managed-infrastructure option for routing, Bedrock Guardrails or related controls. That does not mean those policies appear automatically: the blog says to validate the configured gateway before exposing it to users. A guardrail on model traffic also does not replace local tool permissions or developer review of generated changes.
An LLM gateway fits teams that already operate one or need enforcement in the request path. The repository includes LiteLLM on ECS and Portkey patterns with different identity and operating models. Its README describes LiteLLM as a customer-operated stack and Portkey as a customer-operated EKS data plane with a Portkey-managed control plane. AWS calls a custom gateway the most involved version of this option—not a quickstart. Choose it for a specific unmet requirement rather than adding a service by default.
What the guide does—and does not—say about cost and control
AWS separates Codex OpenTelemetry activity, Bedrock service records, identity evidence and billing data. Client metrics can describe turns, tokens, tool calls and request duration. The Cost and Usage Report is the source for billed usage. For native IAM Identity Center access, the article says CUR 2.0 caller-identity allocation can expose the SSO principal; gateway deployments need gateway records to allocate usage to end users.
The article gives no new rate card and does not establish that Bedrock is cheaper than another Codex inference route. Compare the selected model’s current price, actual billed usage and any gateway or telemetry infrastructure costs before making that claim. AccessAllGPT has not measured those costs or tested subscription entitlements for this setup.
The practical limits are also explicit. Provider, credential, Region and telemetry settings belong in user-level or managed configuration. Repository-local .codex/config.toml and AGENTS.md should not be treated as enterprise enforcement. A working inference call does not approve every repository file, plugin or tool for external transmission. Decide which code and tool output may leave the workstation before widening access.
Why it matters for AI coding teams
For an organization already using AWS workforce identity, the documented native path offers a way to evaluate Codex without immediately introducing another gateway service or model-access identity system. For a team that needs request-level budgets or centralized routing, the same guide makes clear why native sign-in alone may not satisfy the requirement. That is the useful buyer distinction—not a claim that one architecture fits every team.
Our next-step recommendation follows the guide’s sequence: choose a non-production repository, validate the AWS identity and direct model access, then run one harmless read-only Codex task. Use two separately signed-in users to check attribution; one successful login cannot show identity isolation. Verify the intended records and test removing access, accounting for active sessions rather than assuming assignment removal instantly invalidates every credential.
This is a source-backed briefing, not an AccessAllGPT hands-on test. A team should expand only after the exact deployed client, model route, local tool restrictions and rollback procedure work together. There is no demonstrated productivity, security or cost improvement in our evidence set.
A small Codex-on-Bedrock pilot record
Use this as a proposed trial checklist, not as evidence that AccessAllGPT deployed the reference.
Entries stay in this browser tab and are not submitted to AccessAllGPT. Blank responses are copied as [Unresolved].
Name native access, AgentCore Gateway or an LLM gateway, with an owner and the specific requirement it satisfies.
Record Codex version, provider model ID, direct-test inference ID, Region, account access, permitted repository data and local tool permissions.
Check two distinct user identities, one read-only task each, request correlation and actual billing; label estimates separately.
Remove pilot access, handle active sessions according to policy, and demonstrate that a new invocation is denied.
Primary sources
Browse the publication-wide evidence index →
- OpenAI Codex on Amazon BedrockAWS · Reviewed: Displayed November 11 publication date; rollout choices; Native AWS Access; model IDs; identity isolation; gateways; telemetry and billing; configuration boundaries; cleanup · Retrieved · Supports: AWS’s current deployment guidance, local execution architecture, native pilot recommendation, example model identifiers, Region/access caveats, distinct evidence sources and staged rollout and rollback requirements. Does not establish first availability or a new model launch.
- Guidance for Codex on AWS — READMEopenai-on-aws reference repository linked by AWS · Reviewed: Choose a Rollout Path; LiteLLM request flow; client authentication; telemetry; deployment-pattern ownership · Retrieved · Supports: Documents native SigV4 credentials, workstation tool execution, gateway request flow and the different operating and identity models for native access, LiteLLM, Portkey and AgentCore.
- Quick Start: Native AWS Accessopenai-on-aws reference repository linked by AWS · Reviewed: Use-this-pattern criteria; automated validation; identity flow; prerequisites; CloudFormation baseline; permission-set assignment; developer configuration overview · Retrieved · Supports: Documents IAM Identity Center prerequisites and the native access runbook, explicitly describes soft monitoring as alerts rather than blocking, and provides an isolated validation workflow with optional real Codex execution.
Limitations
Documentation-only reporting retrieved November 12, 2026. We deployed no AWS resources, tested no account entitlement, model call, CLI configuration, gateway, identity isolation, local tool policy, bill or rollback. No minimum Codex version, universal regional availability, new price, context specification or performance gain is established by this report. Reference repository files are mutable and deployed behavior must be checked against the actual version and AWS account.
Disclosures
AccessAllGPT received no payment, credits or private briefing for this report. AWS and OpenAI did not review or endorse it. AccessAllGPT Research is operated by NeuralArc, is independent, and is not affiliated with AWS or OpenAI. Publication-wide relationships are listed on the disclosures page.